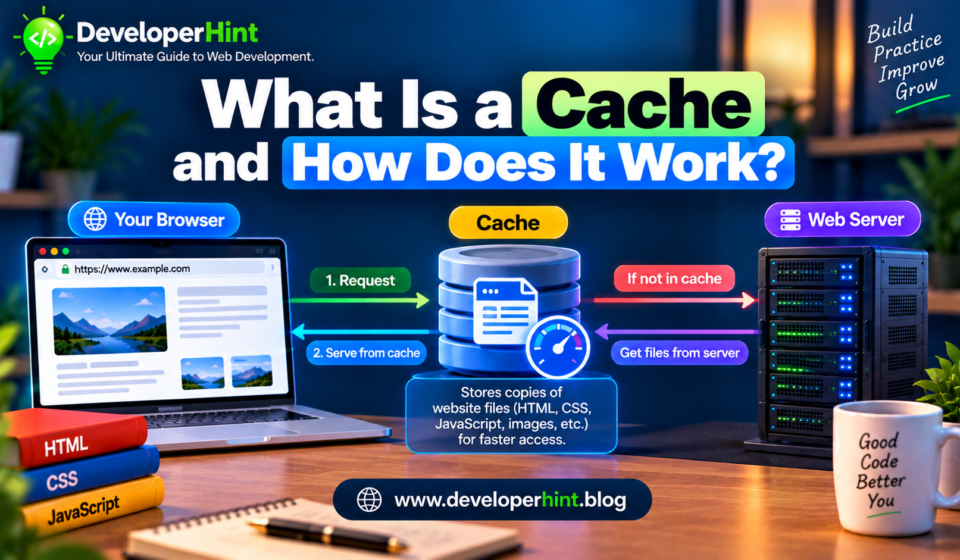

Open a site you’ve never been to and watch it load. Then open it again. The second time, it almost always feels quicker, sometimes dramatically so, and nothing about your internet connection changed. What changed is that your browser kept some of what it downloaded the first time and reused it.
That’s a cache. It’s a stored copy of something that was slow or expensive to get, kept somewhere closer or faster, so the next request can skip the expensive part. The idea is old and shows up at every level of computing, from the memory inside your processor to the servers that deliver video to millions of people. Once you recognize the pattern, you start seeing it everywhere, and you start understanding why certain bugs happen only after you deploy.
The Vocabulary You Need
A handful of terms come up in every caching conversation, and they’re simpler than they sound. When a request finds what it needs in the cache, that’s a hit. When it doesn’t, and the system has to go get the data from the original source, that’s a miss. The proportion of requests that hit is the hit ratio, and it’s the number people usually care about when they tune a cache.
Cached data doesn’t live forever. Most caches attach a TTL, short for time to live, which is how long a copy counts as fresh. After that, it’s stale and has to be checked or replaced. When a cache runs out of room, it evicts something to make space, and a common rule is to drop whatever was used least recently, known as LRU. And when the original data changes and the cached copy is now wrong, you need to invalidate it. That last one is where most of the pain lives, and we’ll come back to it.
Caches Exist at Every Layer
A single web request can pass through several caches before it reaches the code you wrote.
| Layer | Where It Lives | What It Saves |
|---|---|---|
| CPU cache | Inside the processor | Trips to main memory |
| DNS cache | Your OS, browser, and resolver | Repeated domain lookups |
| Browser cache | The visitor’s device | Re-downloading files and responses |
| CDN cache | Servers spread around the world | Distance to your origin server |
| Application cache | Memory on your servers, or Redis and Memcached | Repeating expensive computations and queries |
| Database cache | Inside the database engine | Re-reading data from disk |
Each one trades a bit of freshness for speed. As a web developer, you mostly control the middle three: the browser, the CDN, and your own application. That’s where the rest of this post lives.
How the Browser Cache Decides What to Keep
Your server doesn’t push files into the browser cache. It sends a response with headers, and the headers tell the browser how long it may reuse the file. The main one is Cache-Control:
HTTP/1.1 200 OK
Content-Type: text/css
Cache-Control: public, max-age=86400
That says any cache may store this file, and it stays fresh for 86,400 seconds, one day. For the next day, the browser won’t even contact the server for it. It just uses its stored copy, which is why cached pages can load instantly and even work offline in some cases.
The Directives That Matter
max-age sets the freshness lifetime in seconds. public allows shared caches like CDNs to store the response, while private restricts it to the visitor’s own browser, which is what you want for anything personalized. And then there are two directives that sound alike and do very different things, which trips up a lot of people.
no-store means exactly what it says: don’t keep a copy anywhere. Use it for sensitive responses. no-cache does not mean “don’t cache.” It means the browser may store the file but must check with the server before using it each time. If you want a response never to be stored, no-cache is the wrong choice.
What Happens When a Cached File Goes Stale
A stale copy isn’t automatically thrown away. The browser can ask the server whether its copy is still good, using a validator. The server includes one in the original response, usually an ETag, which is a fingerprint of the file’s contents:
HTTP/1.1 200 OK
ETag: "33a64df5"
Cache-Control: max-age=60
Once the minute is up, the browser sends the fingerprint back with its next request:
GET /styles.css HTTP/1.1
If-None-Match: "33a64df5"
If the file hasn’t changed, the server answers with a tiny 304 Not Modified and no body, and the browser reuses what it has. If it has changed, the server sends the new file with a fresh 200. You save the download but not the round trip, which is a good compromise for files that change unpredictably.
The Deploy Problem and How Fingerprinted Filenames Solve It
Here’s a situation almost every developer meets. You deploy a fix, refresh, and everything looks right. Then a user reports the old broken version. The cause is usually a long max-age on a file whose name never changed: the browser has a copy it considers fresh, so it never asks for the new one.
The standard fix is to put a fingerprint in the filename itself. Instead of app.js, you ship app.3f9a1c7b.js, where the hash comes from the file’s contents. When the code changes, the name changes, and the browser treats it as a completely different file that it has never seen. Build tools like Vite and webpack do this for you automatically.
That unlocks an aggressive strategy for those files, because a hashed file can never be stale. Its name changes whenever its content does:
Cache-Control: public, max-age=31536000, immutableThat’s one year, and immutable tells the browser not to bother revalidating even on a reload. The one file that can’t use this trick is your HTML page, because its name has to stay index.html or whatever the URL maps to. So HTML gets a short lifetime or no-cache, and it points at the new hashed files as soon as they exist. That combination, short-lived HTML pointing at permanently cached assets, is behind most fast, correctly updating sites.
Best for: use this as a starting point for headers by file type.
| Resource | Suggested Cache-Control |
|---|---|
| Hashed JS and CSS bundles | public, max-age=31536000, immutable |
| HTML pages | no-cache (store, but revalidate each time) |
| Images without hashes in the filename | A moderate max-age like one day, plus an ETag |
| User-specific API responses | private, with a short max-age or no-store if sensitive |
In Express, you can set a lifetime on static files directly:
app.use(express.static("public", {
    maxAge: "1y",
    immutable: true
}));
Only do that for a folder of fingerprinted files. Applying a one-year lifetime to a folder of files that keep their names is how you create the stale-deploy problem on purpose.
CDN Caching
A CDN is a cache with geography. It keeps copies of your content on servers in many regions, so a visitor in Mogadishu gets files from a nearby machine rather than waiting on your origin server on another continent. That cuts latency for the visitor and traffic for you, and it’s one of the cheapest ways to improve load speed, which matters for the LCP metric we cover in our Core Web Vitals guide.
CDNs read the same Cache-Control headers, with one addition. s-maxage sets a lifetime for shared caches only, so you can let the CDN hold a page for ten minutes while browsers revalidate every time. You can also purge a CDN’s copy through its dashboard or API when you need an update to appear everywhere right away.
There’s one mistake here worth stating clearly, because the consequences are bad. If a response is personalized, like an account page or anything that depends on a login cookie, and it goes out marked public, a shared cache can store it and serve it to the next visitor. People have ended up looking at each other’s data this way. Anything tied to a user should be private or no-store. The cookie guide explains how login sessions work and why those responses are personal.
Caching Inside Your Own Application
Browser and CDN caches handle files and responses. For work your server does itself, like a slow database query or a call to someone else’s API, you cache the result in your application. The usual pattern is called cache-aside: check the cache first, and only on a miss do the real work and save the answer for next time.
const cache = new Map();

async function getProduct(id) {
    const cached = cache.get(id);

    if (cached && cached.expires > Date.now()) {
        return cached.value; // hit
    }

    const product = await db.findProduct(id); // miss: do the slow work
    cache.set(id, { value: product, expires: Date.now() + 60_000 }); // 60 second TTL

    return product;
}
That in-memory Map works for a single server, but it disappears on restart and isn’t shared between multiple servers. Once you run more than one instance, teams typically move this to Redis or Memcached, which hold the cache in a separate fast service that every instance can read. The pattern stays the same. Only the storage changes.
The sixty-second TTL is a deliberate choice. A product page that’s up to a minute out of date is usually fine, and it can turn a thousand database queries into one. A stock count on a checkout page is a different story. Deciding how stale is acceptable for each piece of data is the actual design work in caching.
The Hard Part: Keeping Caches Honest
There’s an old joke that the two hard problems in computer science are naming things and cache invalidation. It lands because every cache is a promise that a copy is close enough to the truth, and the original keeps changing underneath it.
You have a few options for keeping that promise. The simplest is to let the TTL expire and accept some staleness, which is fine more often than people expect. When that’s not good enough, you can delete or update the cached entry whenever the underlying data is written, so the next read rebuilds it fresh. Another approach is versioning the key itself, like product:42:v7, so a change simply starts using a new key and the old one ages out.
There’s also a middle path built into HTTP called stale-while-revalidate. With Cache-Control: max-age=60, stale-while-revalidate=300, the browser can show a slightly stale copy instantly while it fetches a fresh one in the background. The visitor gets speed, and the next visit gets current data. For content like article listings or dashboards, that tradeoff is often exactly right.
Seeing Your Caches at Work
Open DevTools and go to the Network tab. Reload a page you’ve visited and look at the Size column. Entries that say “(disk cache)” or “(memory cache)” never touched the network at all. A request showing status 304 went to the server, got told nothing changed, and reused its copy. Click any request and check the response headers for Cache-Control, ETag, and Age, which reports how many seconds a shared cache has held the response. CDNs usually add their own header too, such as cf-cache-status on Cloudflare, which says plainly whether you got a hit or a miss.
One DevTools habit will save you hours: tick “Disable cache” in the Network tab while you work. It only applies while DevTools is open, but it stops your own browser from fooling you. When you want to test what a real returning visitor sees, untick it, or use a hard reload (Ctrl+Shift+R, or Cmd+Shift+R on a Mac) to bypass the cache for one load.
A Question to Ask Before Blaming the Code
When something works on your machine but not for users, or a change you deployed doesn’t show up, suspect a cache before you suspect your logic. Then narrow it down by layer. Does a hard reload fix it? Then it’s the browser. Does it differ by region, or look fine on a direct request to your origin server? Then it’s the CDN. Does the API return old data while the database has new data? Then it’s your application cache. Each layer has its own headers and its own way to clear it.
The useful question for every cached thing you build is a short one: how stale is acceptable here, and who is allowed to store it. Answer that, and most of the headers and TTLs choose themselves.
Discover more from Developer Hint
Subscribe to get the latest posts sent to your email.
Content Disclosure
This content was created with the assistance of AI tools and thoroughly reviewed, fact-checked, and refined by a human editor to ensure accuracy, clarity, and usefulness for readers.Advertisements